Nutritional Data Clustering
Semantic categorization of 10,000+ USDA food ingredients using unsupervised learning.
Data Scientist
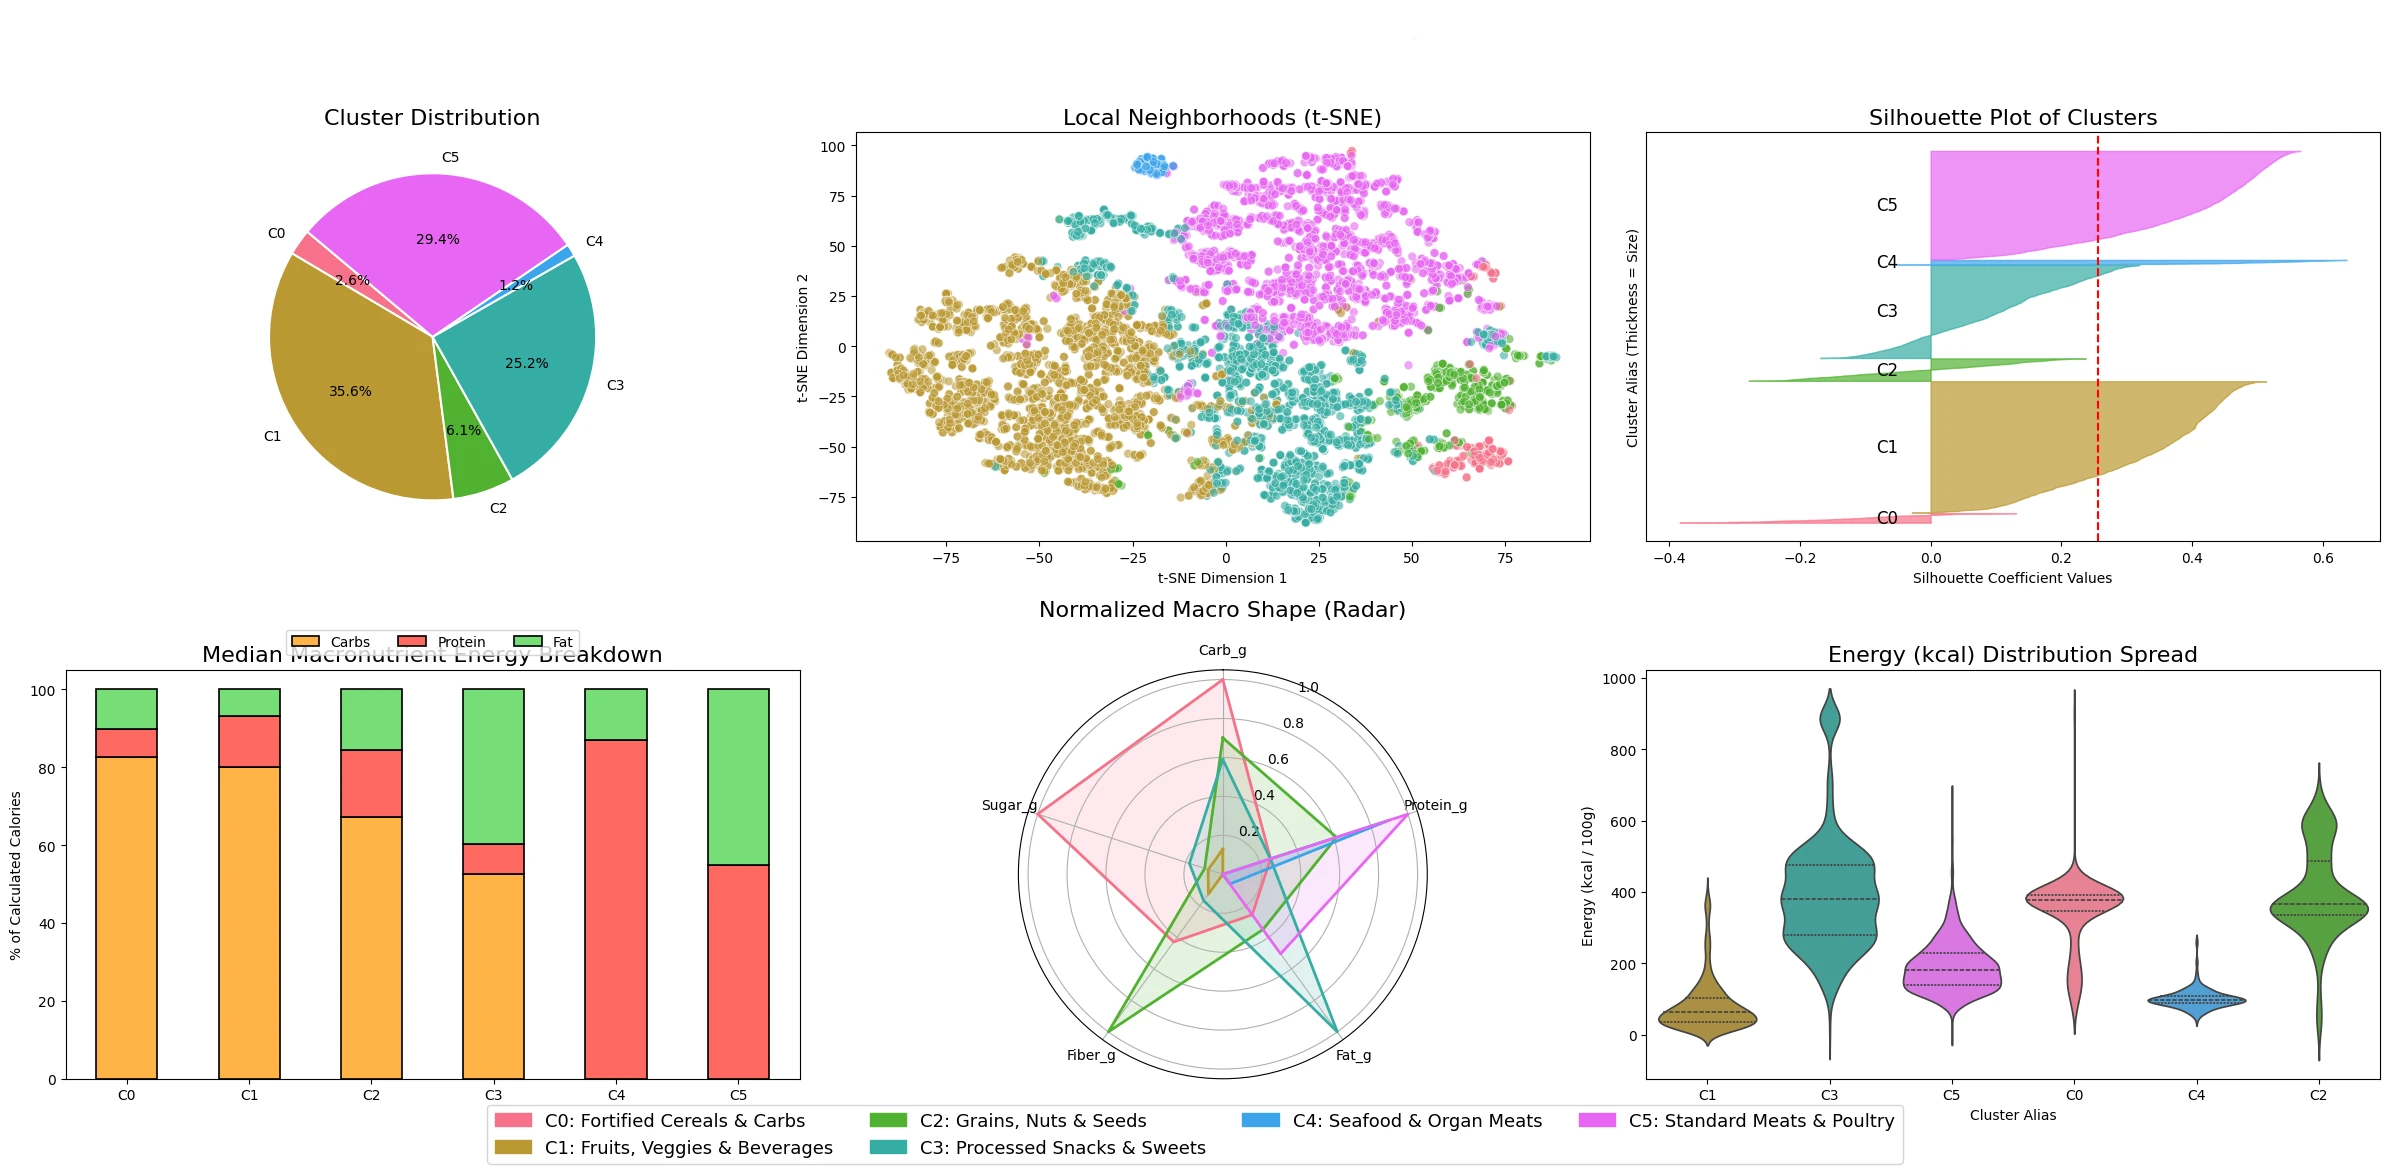
This project focused on the semantic categorization of over 10,000 USDA food ingredients using unsupervised learning techniques.
Key techniques included rigorous data preprocessing utilizing Log1p transformations, standard scaling, and Atwater equation validation. Custom feature engineering was performed by developing specific nutrient ratios to better capture essential dietary relationships. For dimensionality reduction and visualization, techniques such as t-SNE and UMAP were applied.
The project involved comparing various clustering algorithms, including DBSCAN, HDBSCAN, and K-Means. The winning approach was a K-Means model with k=6, which successfully mapped complex mathematical coordinates into human-interpretable dietary categories.